GyRot: Leveraging Hidden Synergy between Rotation and Fine-grained Group Quantization for Low-bit LLM Inference
IEEE International Symposium on High-Performance Computer Architecture, 2026
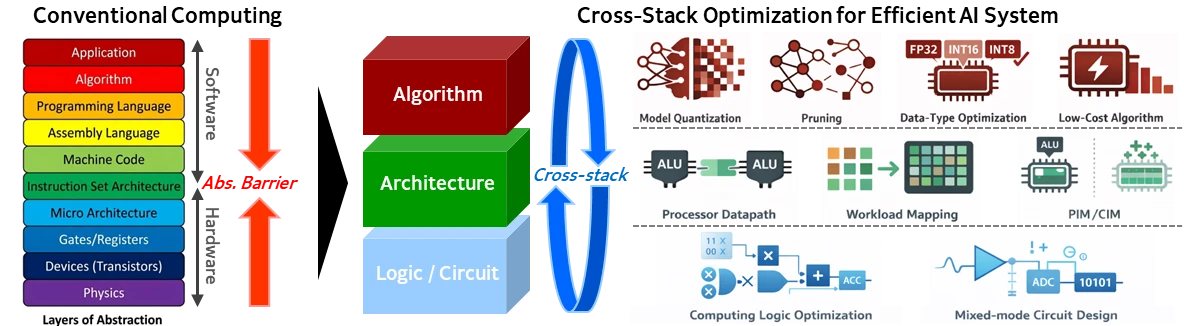
Cross-stack optimization for efficient AI systems. Instead of tuning hardware and software separately, we co-design the chip, the architecture and the algorithm so that generative AI runs efficiently on the device.
Algorithm
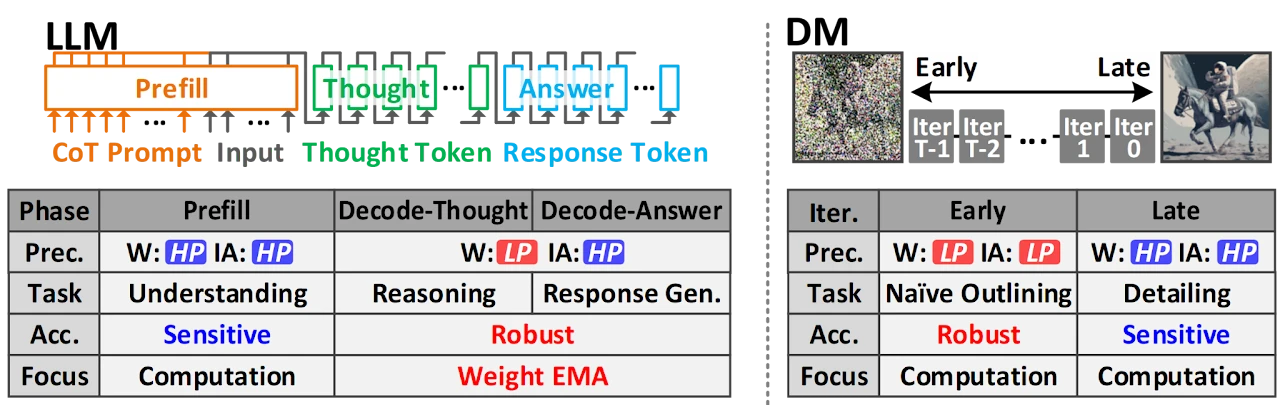
Lightweight AI algorithms designed around real hardware constraints.
We develop quantization algorithms that hold up across diverse generative AI models, so the same compressed model runs well on many kinds of hardware. We also design adaptive algorithms that spend computation according to how much each piece of data matters, cutting overhead while keeping accuracy high.
IEEE International Symposium on High-Performance Computer Architecture, 2026
IEEE Journal on Emerging and Selected Topics in Circuits and Systems, 2025
IEEE/ACM International Symposium on Microarchitecture, 2026 * equal contribution
Architecture
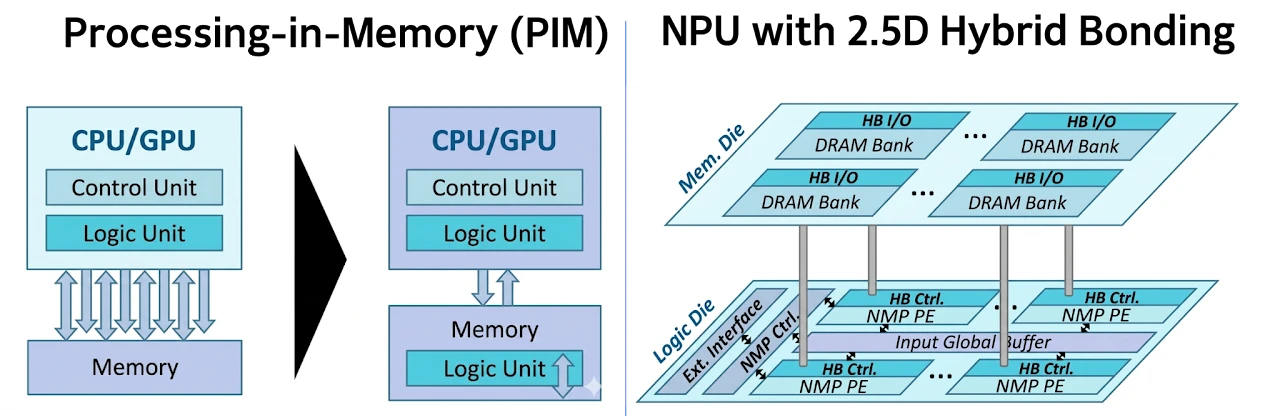
AI systems built around next-generation memory.
We investigate architectures such as processing-in-memory (PIM) that merge memory and compute to get past the data-movement bottleneck. Our designs also account for 2.5D and 3D integration and packaging to raise system-level density and performance.
ACM/IEEE Design Automation Conference, 2026
IEEE International Symposium on Computer Architecture, 2026
IEEE International Solid-State Circuits Conference, 2026
Chip
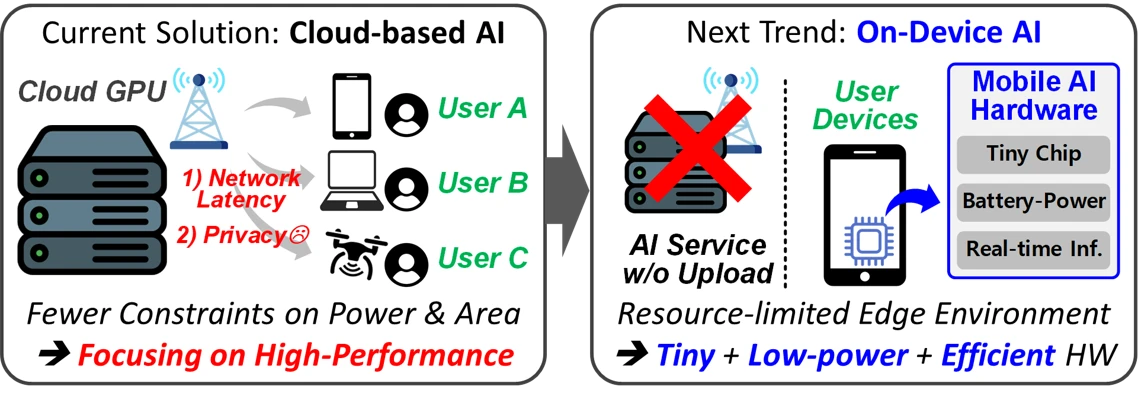
Low-power, high-efficiency AI silicon for on-device platforms.
We engineer AI chips that work within the tight power, area and memory budgets of mobile and edge devices. Our work spans lightweight hardware logic, compute-in-memory macros and specialized datapaths that make real-time generative AI inference possible on the device itself.
IEEE International Solid-State Circuits Conference, 2026 Invited to JSSC
IEEE International Solid-State Circuits Conference, 2025 Invited to JSSC
IEEE International Solid-State Circuits Conference, 2026
Oct. 2026 – Sep. 2029
6G FR3 광대역 고효율 송신기를 위한 AI 기반 PA-DPD 및 Computing-In-Memory 연산 가속 회로 통합 설계
한국연구재단 한-핀란드 공동연구사업
Jul. 2026 – Dec. 2030
멀티모달 센서-NPU 통합 피지컬 AI 반도체 연구단
InnoCORE 출연연 연계형 연구과제
Mar. 2026 – Dec. 2028
PIM 반도체 설계연구센터
과학기술정보통신부 PIM 인공지능 반도체 핵심기술개발
Mar. 2026 – Feb. 2031
온디바이스 AI 에이전트와 테스트–타임 스케일링을 위한 멀티 피델리티 LLM 기반 NPU–SoC 및 LPDDR–PIM 아키텍처
한국연구재단 세종과학펠로우십